A new ERP just runs your old garbage faster
Every AI roadmap I've seen this year assumes a foundation most organizations don't have: clean, governed, AI-ready data. The migration you're running in 2026 and 2027 is the last good chance to fix that before the bill comes due.
I've watched the same cycle run for 25 years. A company buys a new ERP to escape the mess of the old one. There's a heroic go-live and everyone is relieved. Then the customizations creep back in, the master data drifts and the workarounds pile up, until a decade later someone stands up in a steering committee and says it's time for a new ERP to escape the mess of this one. The platform changes, but the mess stays remarkably consistent.
AI is the newest reason to do it right this time, and a better reason than most, because AI acts on your data in a way the old reporting tools never did. Until now the cost of bad data sat in a dashboard nobody trusted. Now it posts to the ledger, screens the candidate and releases the order. Garbage in used to mean a bad report. Now it means a bad decision, made fast and at scale by a system that sounds certain.
Seven questions an executive asks me about AI and their data
- Is our data good enough for AI?
- If an AI project fails, don't we just lose the money?
- What do our old customizations have to do with AI?
- Can't we lift and shift now and clean up later?
- What are the companies getting results doing differently?
- What does AI-ready data actually take?
- Why fix it now, in the middle of a migration?
For most organizations, no, and they know it.
The vendors sell the AI as the hard part. The data underneath is harder, and the research is blunt about it.
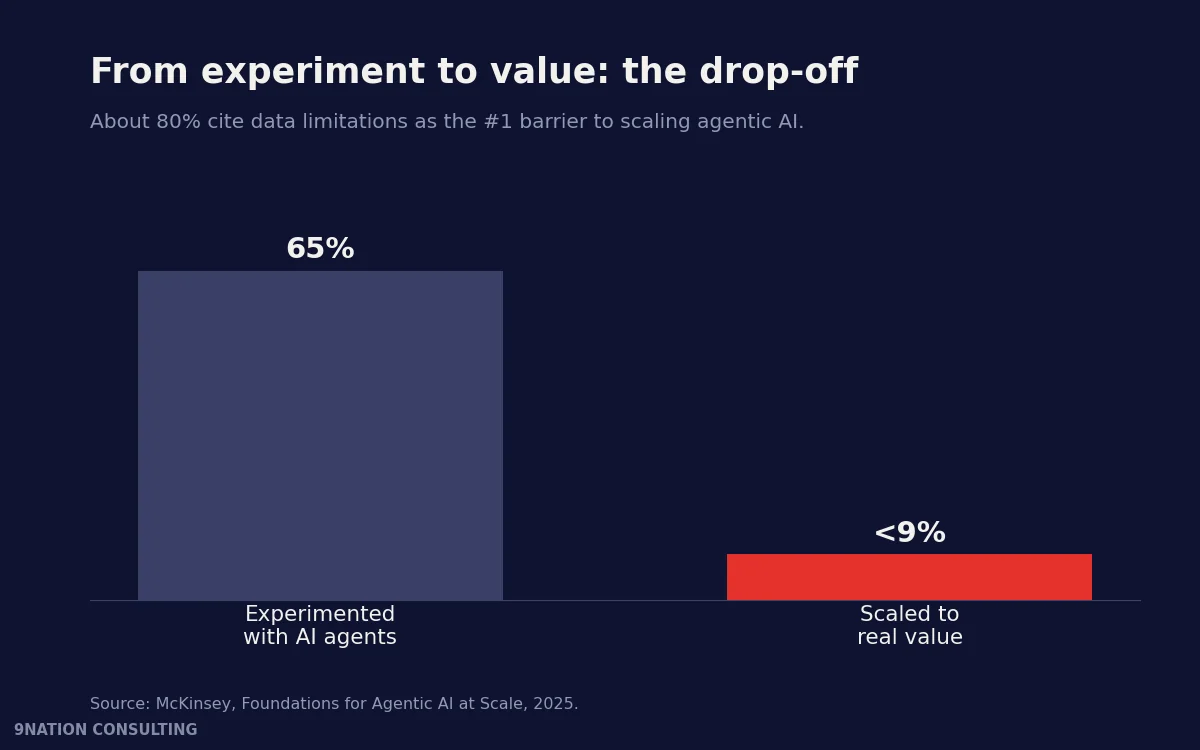
Gartner expects organizations to abandon 60% of AI projects through 2026 because the data isn't ready to support them, and found that roughly 63% of organizations either lack the right data management practices for AI or aren't sure whether they have them. Precisely's annual study landed on the number that should stop a CIO cold: 12% of organizations say their data is of sufficient quality and accessibility for AI. McKinsey found about 80% of companies name data limitations as the main roadblock to scaling agentic AI.
What holds them back is the unglamorous state of their master data and the discipline of their processes, far more than model choice, vendor choice or compute. You can buy the best agents on the market and bolt them onto a foundation that collapses the moment they hit production.
Losing the money is the better outcome. The expensive one is a project that ships and is confidently wrong.
A human analyst working with shaky data hesitates. They sense something's off, they caveat it, they go and check. An agent doesn't pause to frown at the number the way your best analyst would. Point it at inconsistent vendor records, or a cost center hierarchy that three departments maintain three different ways, and it acts, cleanly and quickly, with nothing to tell you anything went wrong. The wrong output looks as polished as the right one.
That makes the 60% abandonment figure the optimistic reading. Those projects at least failed in the open, before they did damage. The worse case is the project that ships on a shaky foundation and produces plausible, well-documented wrong answers for a year before anyone reconciles closely enough to notice.
A lot. Every one of them makes the vendor's AI harder to switch on.
This is where it connects to the migration most of you are already planning. Every non-standard modification you carry, every custom object and every bypass of the supported extensibility layer used to be technical debt, a vague future problem. Now it's a concrete near-term invoice, and AI is the line item.
That's what the clean-core push is about. In 2025 SAP formalized it into a compliance model that runs from Level A to Level D. Level A is fully clean: extensions sit safely outside the core, and AI features switch on as shipped. Level D is years of unmanaged direct modification: upgrades are blocked, and AI can't turn on without major remediation first.
SAP names data as one of its five clean-core dimensions on purpose. Even if your code is spotless, dirty master data disqualifies you. Oracle built its Fusion agents to run on the suite's shared data model and governance, and they depend on both. Workday's agents only behave on well-governed tenant data. On any of them, misconfigured business processes and duplicate workers produce confidently wrong AI.
All three vendors build their AI features on the assumption of a standardized, clean data model. Custom code already runs past 30% of the scope in a typical brownfield migration, and none of it makes you readier for AI. Your 2015 customizations cost you once on the migration and again on every AI feature they block.
You can, but the mess moves with you.
The fastest migration path is appealing because it's fast. It's also how the mess survives the move. A brownfield lift and shift brings your customizations and your data quality problems straight across the bridge. Duplicate records stay duplicated, stale records stay stale, and you spend a fortune to arrive at the same spaghetti, freshly hosted.
Greenfield, or a selective bluefield transition that lets you bring some history and leave the rest, exists because enough programs learned this lesson at full price. No single approach wins every time. The choice should be deliberate, made knowing exactly which problems you're choosing to carry forward, and paired with real data cleanup before you move. Don't count on fixing it later. Later, the hypercare team is too busy keeping the lights on.
They spend up to four times more on data.
If you need the business case in one line for your CFO, Gartner supplied it in 2026: organizations with successful AI outcomes invest up to four times more, as a share of revenue, in data quality, governance and AI-ready people than the ones getting poor results. Their edge is data discipline, much more than model selection.
That discipline is rarer than anyone admits. One industry survey found only 4% of organizations have high maturity in data governance and AI governance at the same time. Most have a little of one or a little of the other, and almost nobody has the combination that agent-driven AI at enterprise scale needs. I expect that gap to sink most AI ambitions in 2027, slowly, as companies realize the foundation can't bear the weight.
Mostly ownership and steady upkeep. None of it is mysterious, but it doesn't demo well.
It starts with ownership. Every critical data domain (vendor, customer, material, cost center, employee) needs an accountable owner with real authority. A steward who files tickets nobody actions doesn't count. Data quality standards for completeness, freshness and accuracy get written as commitments that domain teams are held to. Master data management has to be a standing discipline, because the drift starts again the moment a one-time cleanup ends.
Then there's what makes data trustworthy to a machine: lineage you can trace, which regulators increasingly require for high-risk AI anyway, a catalog with enough metadata that an agent and an auditor both know what they're looking at, and an extensibility discipline that keeps the core clean so the platform's AI can run. Architecture governance and data governance have to move together. You can't sit a Level A clean core on Level D data and expect the agents to behave.
Because a migration already puts everything on the table, and the deadlines arrive within 18 months.
Several forces land in the same 18-month window: SAP's 2027 deadline, the quarterly cadence of the cloud platforms, and agentic features rolling out across every suite. The timing is inconvenient, but it's also the opportunity. A migration is the rare moment an enterprise gets to make a deliberate architectural choice instead of inheriting one: cleaning the data, rationalizing the process and keeping the core clean before the agents arrive.
The alternative is to lift and shift, hit the date, declare victory and find out you spent a fortune to run your old garbage faster, with AI standing by to explain, confidently, why the garbage is wrong.
The technology was never going to be the hard part. What's hard is fixing the foundation before someone with a fee incentive tells you it's good enough. It's worth having someone in the room who's paid to insist on it.
Sources
Gartner, "Lack of AI-Ready Data Puts AI Projects at Risk" (Feb 2025), for 60% abandoned through 2026 and 63% lacking or unsure of data practices. Gartner (Apr 2026), for successful-AI organizations investing up to four times more in data foundations. Precisely, Fourth Annual Study (2025), for 12% AI-ready, 64% citing data quality, and 67% not fully trusting their data. McKinsey, "Foundations for Agentic AI at Scale" and "Bridging the Great AI Agent and ERP Divide" (2025). DATAVERSITY 2025 Trends in Data Management, for 4% high maturity in both data and AI governance. SAP clean-core model, Levels A to D, SAP News (Aug 2025); PwC S/4HANA migration risks, for custom code past 30% of scope. Oracle Fusion Agentic Applications (Mar 2026); Workday Data Cloud (Sep 2025).
Fix the foundation before you scale AI on top of it.
If your AI roadmap is riding on the data underneath your ERP, an independent read on readiness is the cheapest insurance you will buy.